Enterprise AI · RAG + Agent

面向企业知识库的可验证 AI AgentA verifiable AI Agent for enterprise knowledge

基于 LangGraph 与混合检索,跨文档查证答案、对照政策变化,并将执行步骤和回答追溯到原文。Built with LangGraph and hybrid retrieval to check facts across documents, compare policy changes, and trace tool calls and answers to their sources.

  • LangGraph
  • Hybrid Retrieval
  • ACL
  • Citation Verification

虚构企业资料 · 可体验问答、Agent 查证与原文核验 · 共享每日额度。正在检查实时服务… 本机离线时仍可查看执行回放。Fictional enterprise documents · ask questions, run Agent tasks and inspect cited evidence · shared daily quota. Recorded runs remain available when the local server is offline.

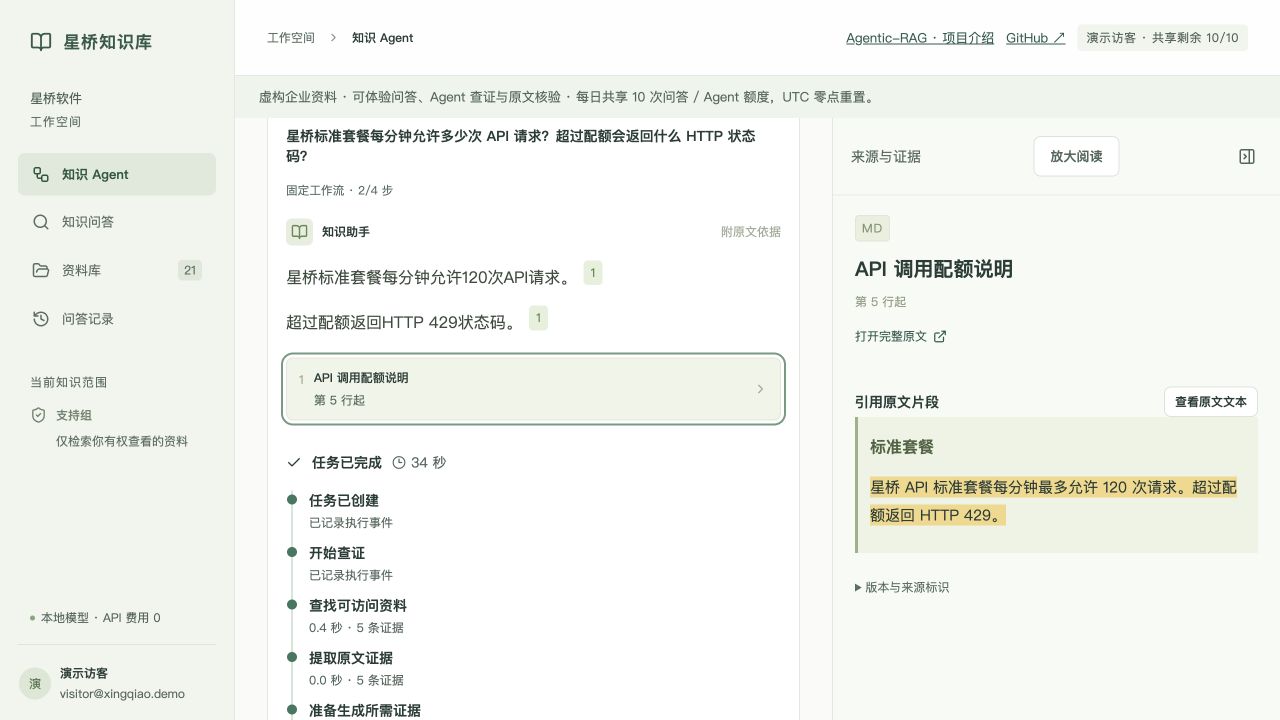
真实 Agent 固定工作流:任务目标、原文引用与实际执行步骤
真实 Agent 执行:先查资料与证据,再返回附引用的答案。点击可放大。A real Agent run: authorized document lookup, evidence retrieval, and a cited answer. Click to enlarge.

产品演示Product demo

先选一个场景,看看系统如何查证Choose a scenario and inspect the evidence

无需本机在线:打开真实执行回放 →Offline-ready: replay a real run →

01 · 一次真实 Agent 执行01 · A real Agent execution

真实执行回放Recorded execution · Workflow

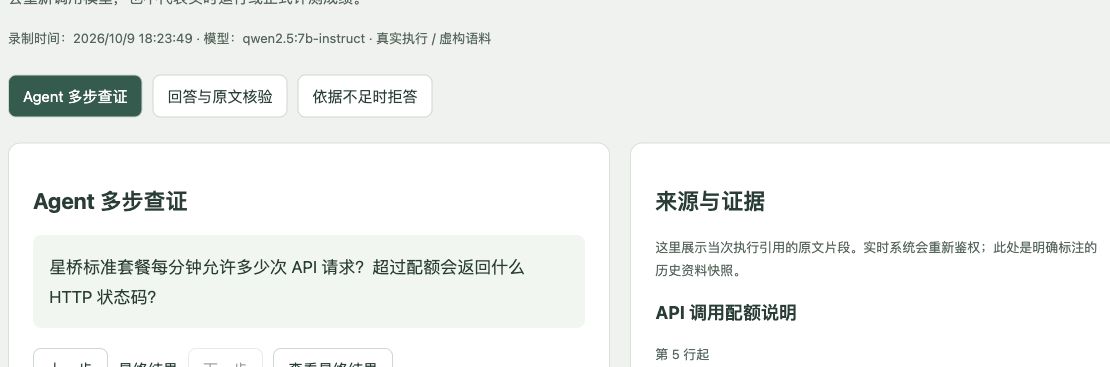
任务Task: 星桥标准套餐每分钟允许多少次 API 请求?超过配额会返回什么 HTTP 状态码?

  1. search_documents5 条证据5 evidence spans
  2. retrieve_evidence5 条证据5 evidence spans
  3. 准备生成所需证据Prepare generation evidence
  4. 检查问题覆盖情况Check answer coverage
  5. 返回核验结果Return the verified result

最终回答Final answer

星桥标准套餐每分钟允许120次API请求。

超过配额返回HTTP 429状态码。

来源Source: API 调用配额说明 · 第 5 行起

逐步回放与原文Replay steps and source
回答、PDF 原文与引用高亮

02 · 回到原文核验02 · Inspect the original source

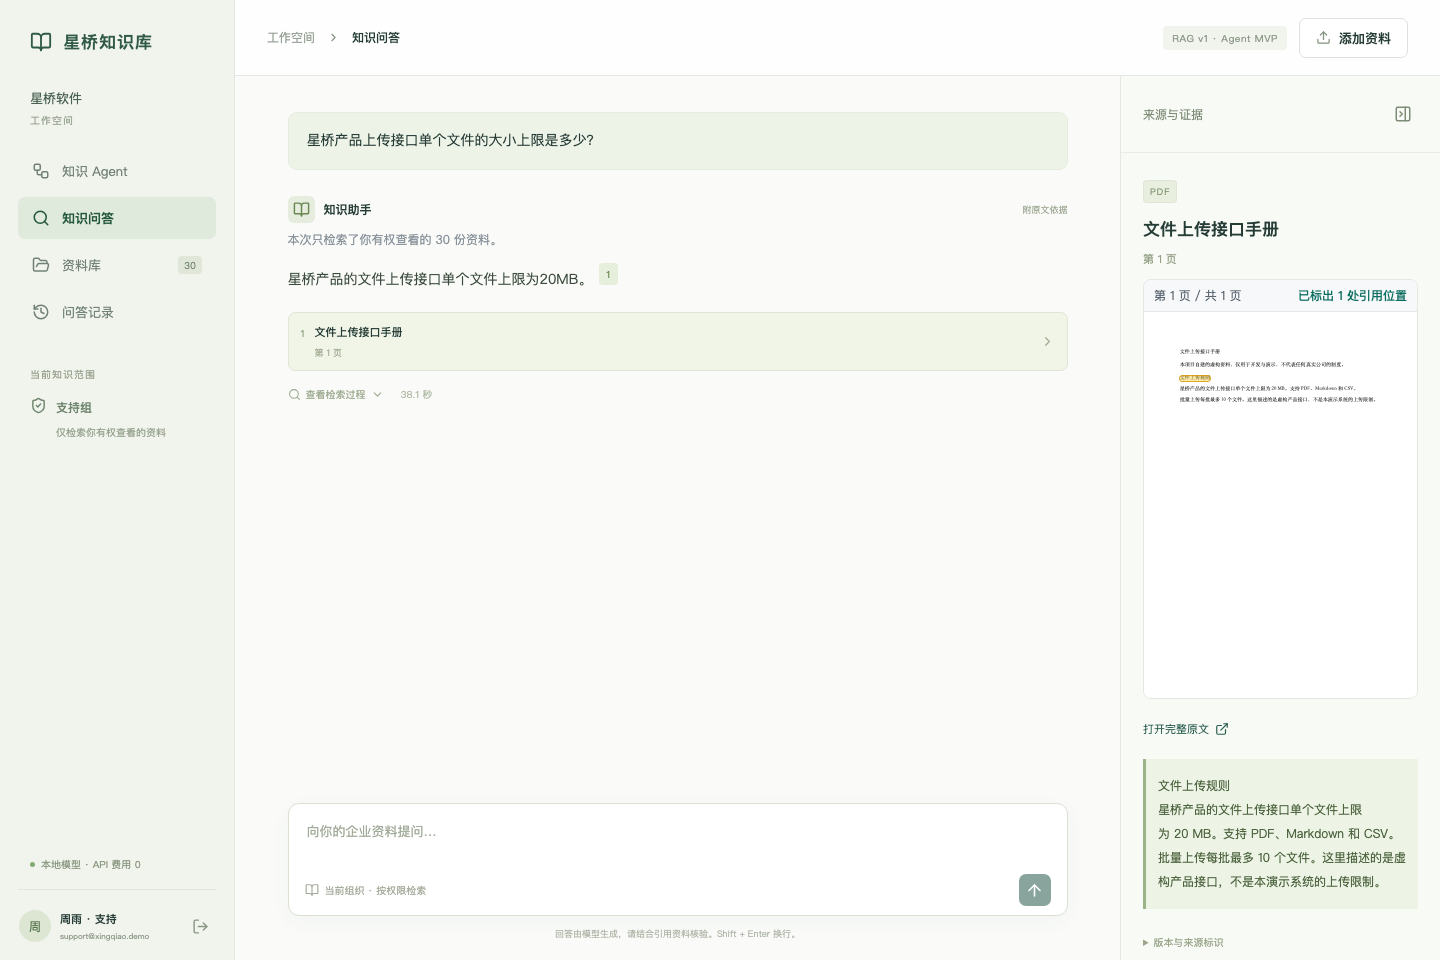
引用定位到 PDF 原文,关键句高亮显示。Citations locate and highlight supporting sentences in the original PDF.

同一份虚构文档在支持组与工程组下的允许和拒绝对照

对照权限边界Compare role boundaries

同一份资料,不同团队的访问权限不同。The same document is accessible only to authorized teams.

再看两张:上传解析与检索调试Two more: upload parsing and retrieval inspector
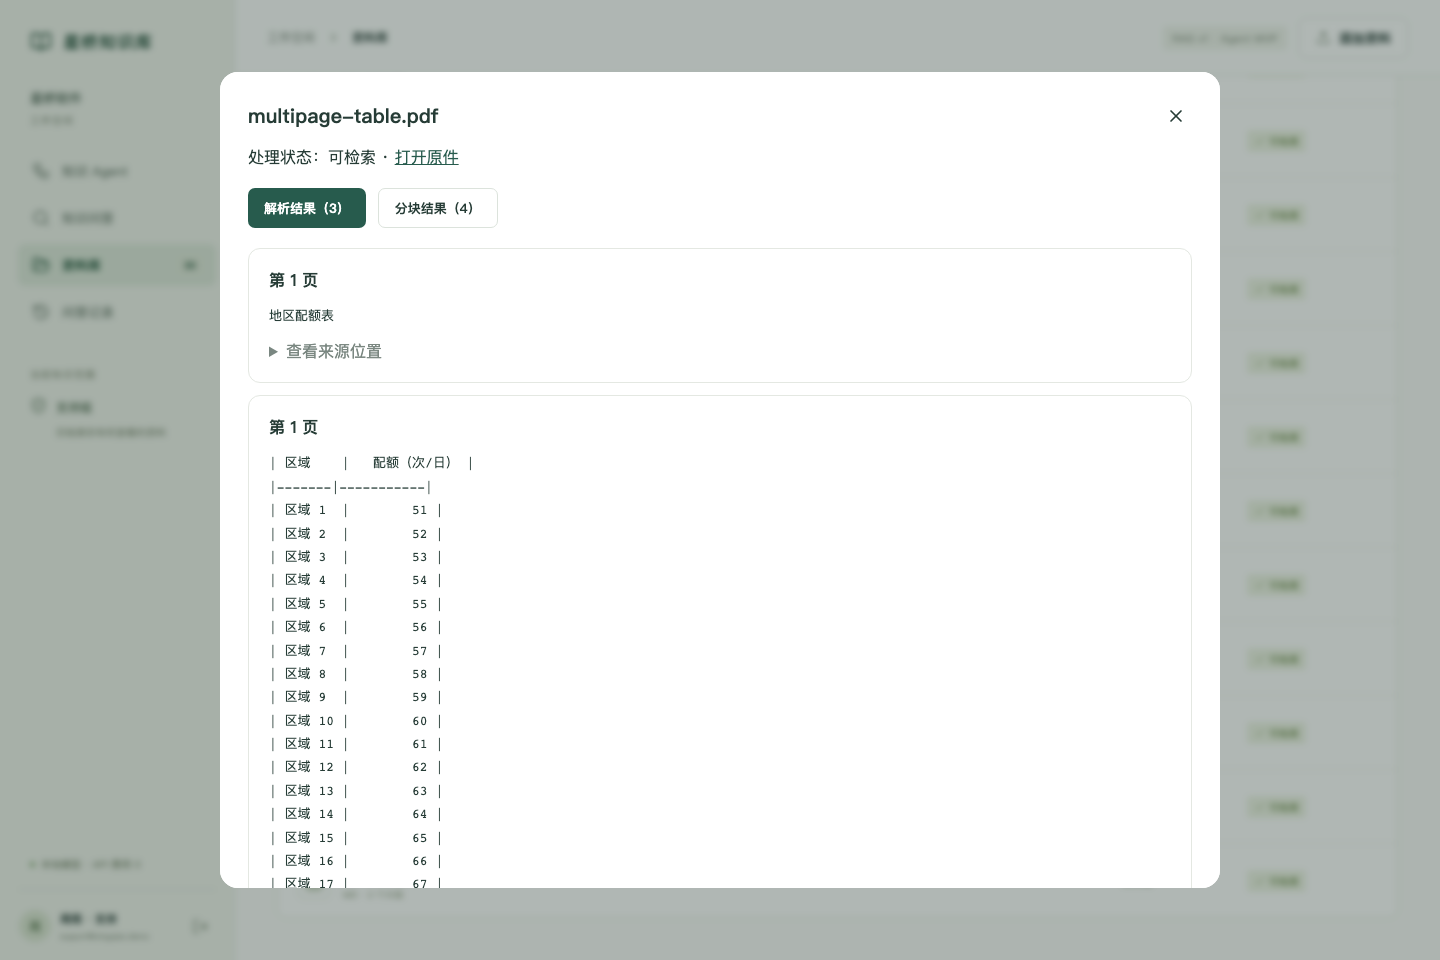
上传与解析

上传一份多页表格 PDF,处理完成后变为可检索,可逐页查看解析结果与分块。Upload a multi-page table PDF; once processed it becomes searchable and its parsed pages and chunks can be inspected.

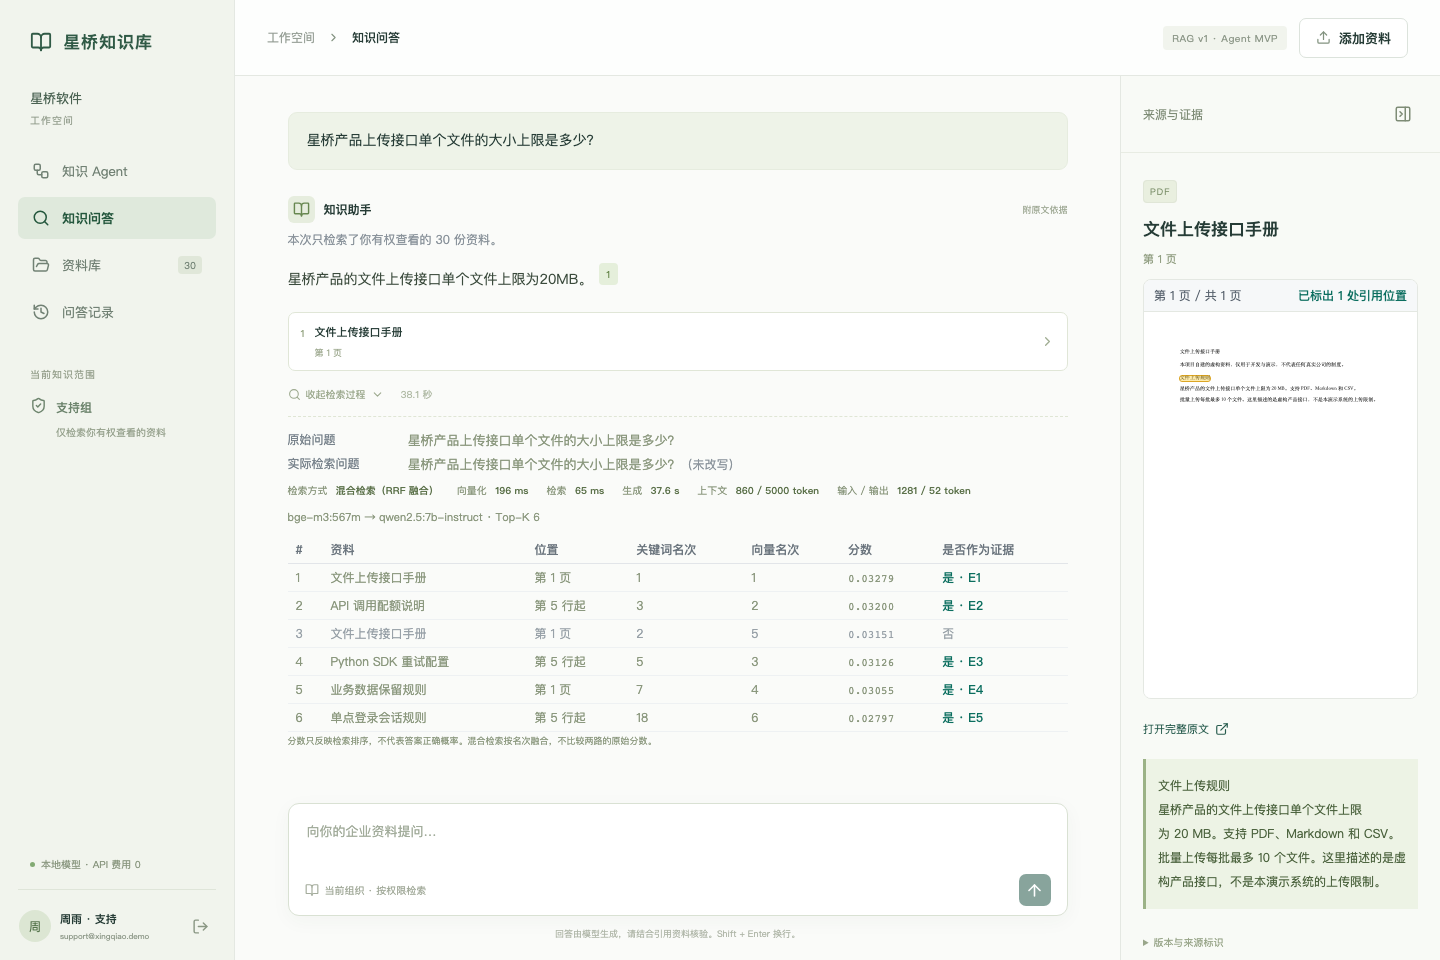
检索调试

检索调试页:检索方式、两路名次,以及哪些候选真正进入了模型。Retrieval inspector: retrieval mode, rank in each path, and which candidates actually reached the model.

核心能力Key features

从 Agent 编排到可核验的企业答案From Agent orchestration to verifiable enterprise answers

LangGraph

多步编排与工具审计Multi-step orchestration and tool audit

LangGraph 管理节点、条件转移与检查点。固定工作流组织检索、取证与生成,实际工具、耗时和证据数量可在任务轨迹中检查。LangGraph handles nodes, conditional transitions and checkpoints. The Workflow coordinates retrieval, evidence and generation, with actual tools, timing and evidence counts in the task trace.

Retrieval + Versions

跨文档查证与版本语义Cross-document evidence and version semantics

BM25 与 BGE-M3 经 RRF 融合检索,多份资料进入同一次查证;版本工具区分历史与生效内容。Hybrid 可依据中间证据补查,效果仍须正式评测。BM25 and BGE-M3 are fused with RRF to gather evidence across documents. Version tools distinguish historical and effective content; experimental Hybrid can request follow-up evidence.

权限进检索,不做事后过滤Permissions inside retrieval, not after it

授权范围是检索查询的一部分,返回前再校验一次。先检索再过滤,意味着敏感资料已经进过排序和生成链路。The authorized scope is part of the query and is checked again before returning. Filtering afterwards would already have sent sensitive text through ranking and generation.

引用可核验,核验不过就不返回Verifiable citations, or no answer

服务端取回真实原文,核对数值、单位、版本与权限后才组装引用;不通过时最多局部修复一次,仍不通过就判定失败。The server fetches the real source and checks values, units, version and access before assembling citations; one bounded repair, then the answer fails.

撤权立即生效Revocation takes effect immediately

撤权提交后的下一个请求就被拒绝,不等索引清理;引用了失权资料的历史记录连提问文本一起隐藏。The next request after revocation is denied without waiting for the index. History entries citing revoked documents are hidden, question text included.

冲突要拿出证据Conflicts need evidence

模型必须交出分属两份文档的两段矛盾原文,系统才报告冲突。加这道门槛前冲突判定精确率只有 4.2%,之后在 147 题开发集上为 11/11。A conflict is reported only when the model produces two contradicting passages from two different documents. Precision was 4.2% before this gate and 11/11 on the 147-question dev set after it.
系统架构Architecture

模型只做语言工作,权限、版本和引用由程序把关The model handles language; code enforces permissions, versions and citations

入口Entry

问答(单轮 RAG)Q&A (single-pass RAG)

追问按规则补全上下文后直接检索与生成。Follow-ups are completed by rules, then retrieved and answered directly.

入口Entry

Agent 任务(异步)Agent task (async)

立即返回 queued,后台 worker 以数据库租约领取执行。Returns queued at once; a background worker claims it with a database lease.

↓
LangGraph

编排:固定 Workflow / Hybrid / Planner / DynamicOrchestration: fixed Workflow / Hybrid / Planner / Dynamic

默认走确定性 Workflow,下一步依赖中间结果时走有界 Hybrid;官方检查点支持中断恢复,累计调用预算由业务层保存。Defaults to the deterministic Workflow, or the bounded Hybrid when the next step depends on an observation; official checkpoints allow resumption while cumulative call budgets stay in the application.

search_documentsretrieve_evidenceopen_documentget_document_versioncompare_versionsverify_chunk_accesssearch_memory
↓
检索Retrieve

权限过滤的混合检索Permission-filtered hybrid search

授权范围写进查询,BM25 与 BGE-M3 向量两路用 RRF 融合。Authorization is part of the query; BM25 and BGE-M3 vectors are fused with RRF.

生成Generate

Qwen2.5 7B · Ollama

模型只能引用带编号的证据片段,不能自己写出处。The model may only cite numbered evidence spans; it never writes a source itself.

校验Verify

引用校验与再鉴权Citation check and re-authorization

服务端取回原文核对数值、版本与权限;不通过最多局部修复一次,否则判定失败。The server re-reads the source to check values, version and access; one bounded local repair, otherwise the answer fails.

↓
PostgreSQL

文档、版本、ACL、任务与工具审计、LangGraph 检查点。决定可见性的是这里,而不是搜索索引。Documents, versions, ACLs, tasks, tool audit and LangGraph checkpoints. Visibility is decided here, not by the search index.

OpenSearch

关键词与向量索引;新版本先建索引再发布,切换失败不影响当前版本。Keyword and vector index. A new version is indexed before it is published, so a failed switch never affects the live version.

RAG 与三种 Agent 策略,分别做什么?RAG and three Agent strategies: when to use each

自主程度是设计选择,不是效果排名。各模式共用授权工具、累计预算与引用校验;正式质量对比仍等待冻结 Core 评测。Autonomy is a design choice, not a quality ranking. Modes share authorized tools, cumulative budgets and citation checks; the formal Core comparison is pending.

模式Mode适合任务与决策方式Task and decision process怎么检查执行Execution evidence当前范围Availability
RAG一次检索即可回答;直接检索、生成与核验。One retrieval pass can answer the question; retrieve, generate and verify.检索结果与原文引用。Retrieved evidence and source citations.公开知识问答Public Q&A
Workflow步骤明确的查证;程序决定检索、补查、取证与停止。Known task stages; code controls retrieval, bounded recovery, evidence and stopping.真实固定流程、两次工具调用与最终结果Recorded flow, two tool calls and a final result默认;访客自动路由也使用此模式Default; visitor auto routing also uses this mode
Hybrid下一步依赖中间证据;模型提出查证意图,程序绑定合法工具与参数。Next steps depend on evidence; the model proposes an intent and code binds valid tools and arguments.条件分支、意图绑定和工具审计;当前回放不含本模式。Conditional branches, intent binding and tool audit; absent from the current replay.本地实验Local experiment
Dynamic Agent模型选择后续工具和参数;调用预算、权限与输出校验仍由服务端约束。The model selects tools and arguments; server-side budgets, permissions and output checks still apply.实际工具选择、拒绝原因与审计轨迹;当前回放不含本模式。Actual tool decisions, rejection reasons and audit; absent from the current replay.本地实验;未证明优于 WorkflowLocal experiment; no proven advantage over Workflow

评测Evaluation

先冻结配置,再看结果Freeze first, then measure

历史已验证结果Historical measured results

80 题冻结留出集80-task frozen holdout
0

越权命中。限定当次运行,不代表未知场景全部安全。Unauthorized hits in that run; not a guarantee for unseen scenarios.

当前主正确率Current headline accuracy
pending

Core Strict Task Success 尚未正式运行与审核,不用历史成绩替代。Core Strict Task Success awaits a frozen, reviewed run; historical scores do not substitute.

查看历史数据与来源Historical data and provenance

工程规模Engineering scope

授权工具Authorized tools
7

受控工具,每次读取都重新鉴权;数量不是性能成绩。Bounded tools that re-authorize each read; a count, not a performance result.

已构建评测包Constructed benchmark package
283

Dev 47 / Core 70 / Security 16 / External 150;不代表全部正式测试完成。Dev 47 / Core 70 / Security 16 / External 150; not all formally evaluated.

网站验收记录 ↗Website verification ↗

评测方法与口径Evaluation method and scoring

RAG、Workflow、Dynamic Agent 与 Hybrid 统一用一套评测包比较。只允许在 Dev 上调参;Core 的方法与消融矩阵在第一次运行前注册冻结,看到结果后不能补配置。主指标是 Core 70 题的严格任务成功率:事实完整、条件与版本正确、引用支持、该拒答时拒答、执行安全,全部满足才算通过。RAG, Workflow, Dynamic Agent and Hybrid are compared on one benchmark package. Tuning is allowed only on Dev; the Core method and ablation matrix is registered and frozen before its first run. The headline metric is Strict Task Success on the 70 Core tasks: complete facts, correct conditions and versions, supported citations, correct refusals and safe execution must all hold.

Dev
47

唯一允许调参的部分The only split used for tuning

Core
70

七类各 10 题 · 7 categories × 10 · 待正式运行not yet run

Security
16

组权限、跨租户、撤权、版本范围Group, tenant, revocation, version scope

External
150

MultiHop-RAG 固定子集,已用过,只作外部回归Fixed MultiHop-RAG subset, already used — regression only

历史实验详情(不同题集与口径)Historical experiments (different task sets and scoring)

历史 · 冻结留出集 80 题(只运行一次)History · frozen holdout, 80 questions (run once)

指标Metric运行前门槛Pre-set target实测Measured
回答状态正确率Answer-state accuracy≥ 80.0%90.0%
字面事实覆盖Literal fact coverage≥ 80.0%81.9%
越权命中Unauthorized hits00
隐藏文档泄漏Hidden-source leaks00
引用身份校验Citation identity check全部通过all valid全部通过all valid

“回答状态正确率”只看该答、该拒、该报冲突的判断是否正确,不等于答案内容的语义正确率;内容层面以字面事实覆盖为准。"Answer-state accuracy" only checks whether the system correctly answered, refused or flagged a conflict; it is not semantic answer correctness. Content is measured by literal fact coverage.

历史 · 检索方式对比(自建开发集 147 题)History · retrieval comparison (147-question dev set)

检索方式RetrievalRecall@5MRR@10回答状态正确率Answer-state acc.
BM25BM250.9840.92784.4%
向量检索Dense vectors0.9030.84085.0%
混合检索(默认)Hybrid (default)0.9350.90089.1%

混合检索的检索指标低于 BM25,端到端却最高:证据只有 4 个位置时,关键是谁占了这 4 个位置。差异未达统计显著(McNemar p = 0.19),因此只能说“实测最优”。Hybrid retrieval scores below BM25 on retrieval metrics yet best end-to-end: with only four evidence slots, what matters is who occupies them. The difference is not significant (McNemar p = 0.19), so it is "best measured", not "proven better".

历史 · 英文外部子集 39 题History · English external subset, 39 questions
检索方式RetrievalRecall@5回答状态正确率Answer-state acc.
BM25BM250.89784.6%
向量检索Dense vectors0.89774.4%
混合检索(默认)Hybrid (default)0.97484.6%

英文语料加 100 份干扰文档。这里混合检索的检索优势明显,与自建语料上的排序相反,提示 BM25 的领先可能来自自建资料的专有名词特征。同一运行的字面事实覆盖率接近 0,因此“回答状态正确率”不代表答案内容正确。English corpus with 100 distractor documents. Hybrid retrieval clearly leads here, the reverse of the in-house ranking, suggesting BM25's lead may come from proper nouns in the in-house corpus. Literal fact coverage in the same run was near zero, so answer-state accuracy does not mean the answers were correct.

工程取舍Engineering decisions

三个被数据否决的常见组件Three common components rejected by the data

展开三组对照实验与选择理由Expand three ablations and their decisions

Cross-encoder 重排Cross-encoder reranking

Recall@5 从 0.935 升到 0.968,端到端几乎不变(p = 0.79),冲突精确率从 100% 降到 92.3%,耗时增加约 22%。已实现,默认关闭。Recall@5 rose from 0.935 to 0.968 while end-to-end barely moved (p = 0.79); conflict precision fell from 100% to 92.3% and latency rose about 22%. Implemented, off by default.

LLM 查询改写LLM query rewriting

四组对照中,不给历史的 LLM 改写与完全不改写的追问召回相同(0.65);收益来自对话历史本身。最终采用零模型调用的规则拼接(0.975)。Across four arms, LLM rewriting without history matched no rewriting on follow-up recall (0.65); the gain came from the history itself. A zero-call rule-based rewrite was kept (0.975).

主题一致性校验Topic-consistency check

为拦“答非所问”而实现。校准发现判对回答的重合度 5 分位是 2,判错的无一低于 3:阈值只会误杀正确答案。已完整回退。Built to catch off-topic answers. Calibration showed the 5th percentile overlap of correct answers was 2 while no wrong answer fell below 3: the threshold could only reject correct answers. Fully reverted.

设计动机:权限、证据与执行边界Design rationale: access, evidence and execution

设计动机Design rationale

为什么不直接用 Codex?Why build workflows and agents instead of using Codex directly?

个人查阅文件、修改代码或处理一次性任务,直接使用 Codex 往往更省事。它也能通过 官方 SDK 集成到应用与工作流。本项目选择维护一套面向多用户的企业知识库服务,将业务规则放在服务端统一执行。For personal file lookup, code changes or one-off tasks, using Codex directly can be simpler. Its official SDK also supports integration into applications and workflows. This project builds a knowledge service for multiple enterprise users, with business rules enforced by the server.

权限与版本是业务规则Access and versions are business rules

检索、读取和任务恢复都检查当前授权,处理租户隔离、撤权及版本范围。这些规则必须在工具与数据层执行,不能只依赖提示词。Retrieval, reads and resumed tasks check current access, tenant boundaries, revocation and version scope. Tools and data access enforce these rules; prompts alone are insufficient.

回答需要可核验的证据Answers need inspectable evidence

引用绑定真实文档、版本与原文位置,返回前再次校验。证据不足、资料冲突及失权引用,也有明确的处理路径。Citations bind to real documents, versions and source locations and are checked before return. Insufficient evidence, conflicting sources and revoked citations have explicit handling paths.

执行过程需要受控且可评测Execution needs controls and evaluation

受控工具、累计预算、审计和持久化状态约束每次执行。RAG、Workflow 与 Agent 用同一套评测比较质量、调用量和延迟。Bounded tools, cumulative budgets, audit logs and persisted state constrain each run. RAG, Workflow and Agent methods share an evaluation package for quality, calls and latency.

保留部署与模型选择Choose deployment and models

当前采用 Ollama 本地推理,自主管理文档、索引及模型部署。这个选择也需要承担本地模型能力和单机延迟的限制。The current implementation uses local Ollama inference and manages its documents, indexes and model deployment. This choice also carries local-model quality and single-machine latency limits.

为什么同时保留 Workflow 和 Agent?Why keep both Workflow and Agent modes?

固定 Workflow 明确组织检索、生成与核验;Agent 模式允许依据中间证据补查或比较版本。两者共用授权工具,按任务需求与评测选择。节点调度、循环和检查点直接复用 LangGraph,项目主要实现企业业务规则。A fixed Workflow organizes retrieval, generation and verification explicitly. Agent modes can request more evidence or compare versions based on intermediate results. Both share authorized tools and are chosen by task needs and evaluation. LangGraph supplies scheduling, loops and checkpoints; project code implements enterprise business rules.

当前尚未接入 Codex;未来即使采用它作为执行者,仍需经过同样的授权工具与输出校验。正式 Core 验收尚未完成,本项目不声称自建 Agent 比 Codex 更强。Codex is not integrated today. A future Codex executor would still need the same authorized tools and output checks. Formal Core acceptance is pending; this project makes no claim that its Agent outperforms Codex.

已知边界Limitations

这套系统还不能证明什么What this project does not yet show